Loyality Oath

The HR department is administering the loyalty oath.  This is annual event.  We are requested to testify, via a form, to all our professional affiliations.  To a degree I am, of course, joking.  This invasion of our personal privacy is motivated by three concerns: concerns about possible conflict of interest (i.e. that the best interests of the employer might not be #1), concern that we might be not do what we are paid to do but rather work on some outside project, and finally that we might leverage the employer’s good name to the outsider’s benefit.  I gleaned that list from the sections of the policy manual the form points to.

Social networks are a particularly interesting test case for looking at issues of the multihoming since of course they are where you make you home.  I have account memberships in about a half dozen different social networking sites; but I don’t actually participate in any of them.  Though that all depends on your definition of social networking site.  If your more generous in your definition, including say all the on-line forums and mailing lists that include a social (v.s. purely on-topic) component then the number of sites I have accounts at explodes.  A quick review of my password wallet suggests the number gets up toward a hundred; the phrase ‘a gross’ seems useful at this point.  An then some percentage of the blogs I read have a social (or community) subtext.

Some of these places are quite social.  The shaving and diet forums for example. The Oil Drum and Crooked Timber are two nice examples of blogs that sustain a community around them.  Others are semi-social; the one for my PDA for example.  It’s worth noting in passing that the social can make it a bit tough to keep the sites useful for their nominal on-topic purpose.

Where you sit changes how you look at the question of multihoming and social networking sites.  If you have a large stake in one; owning LinkedIn for example but even if you have invested a lot of your social energy into a particular one your profession for example, then you are likely to be interested in ways of reducing the degree of multihoming.  There is certainly plenty of literature on how to execute on that.

Lots of people interested in knowledge flows have noticed that that individuals that cross between two social/professional networks often account for critical knowledge transfers.  So if your interested in encouraging that kind of thing then you might be interested in how to manage and enable increased multihoming.  I don’t think I’ve ever worked for employer who failed to consciously, though rarely conscientiously, encourage a modicum of that kind of thing.

Multiple social networks create some diversification, which in turn can be a buffer against various risks.  Two risks bear mentioning.  If a social network goes bad having other networks enables members to exit, but also it enable them to be critical and that critique can be key to fixing what going wrong.  Having multiple social networks also allows members to take risks, not just of criticism, but also to take risks that may do irredeemable damage to their reputation; such risks are much harder to take if there no other network to retreat into.

None of this helps to puzzle out the question of exactly how many of my ‘professional’ associations I should enumerate on this form.  I’m sorely tempted to enumerate the complete list of all the on-line forums I’m a member of to which I both feel some loyalty and have any overlap with my employer’s vast range of activities.  Just for fun.  Oh, but curiously I appear to be in a job category where they decided to wave the requirement.  Well golly, now my feelings are hurt – they don’t seem to care if I’m a two timing disloyal abuser of the brand!
Multihome

Yeah, here’s an idea.  Why can’t I set my Firefox browser to distribute my search randomly across N selected search engines?  That would let me continually test which search engine is coughing up the best results with the least offensive ads.  It would erode the monopoly power of the search engines and increase competition.  Well, why not?

Two-sided networks tend to become highly condensed, in the exaggerated case this is called “winner take all.”  One driver toward condensation is the cost for players on either side to maintain relationships with two competing networks.  You could own multiple computers, and run multiple operating systems, but by and large you don’t.  You could use multiple search engines/portals, but by and large you don’t.  The cost of coordinating two homes tends to make it unusual.

The motivation for maintaining two or more homes seem to come down to competition; but in reducing them to that we lose something.  It helps to back out what the benefits of competition are.  I won’t go into that, but terms like choice, reducing provider pricing power, a modicum of self regulation, and innovation all come to mind.

Motivations for multihoming are, presumably, the a vein that can be mined to find counter vialing forces to the natural tendency of two-sided networks to condense.  You can then draw out those players who most strongly feel the benefit to create advocates for a less condensed market structure.

Intermediaries, middlemen again, seem like one way that can happen.  The irony here is that two-sided networks are, at their heart, about reducing the cost of search out or coordination work with the population on the other sided of the network.  I.e. they reduce the cost of multihoming; and enable interoperability.  This irony is one of the reasons that powerful hub owners tend to swallow the intermediaries adjacent to them – the adjacent intermediaries are a source of competitive threat; not because they compete but because they can enable other competitors.

When Google pays the Firefox folks for premiere slot in the UI they are, of course, working around the problem.

Rich Relationship

I’ve been musing about Google’s acquisition of Double Click.

I have a friend who had a problem. When you put his name into Google the results consisted entirely of articles about a contentious event he was peripherally associated with. He spend 3 years engineering other materials on the web, including soliciting links from me and other friends, to drive that drivel off the first page of “his” results. Here’s a guy with an impressive resume of fine work; so the phrase slander comes to mine.  We are all coming to fear Google; because it can casually can destroy.

I’ve mentioned before Double Click is very likely the largest identity provider on the net. They manage that trick by avoiding the hard problem: moving the installed base. They don’t try to change the installed base of browsers. They don’t try to get the installed base of users to sign up. They adopt the gossip model for identity, they build statistical models based on gossip. They sell the gossip models to firms. Part of their payment is gossip about the users.

I hadn’t noticed before how this is similar to Google’s scheme for modeling the value of sites. In original Google they build statistical models of sites based on the link graph. (Obviously the data that web bugs collect is can improve those models).

When I first began thinking about Double Click as an identity provider I was more focused on how evil they appear because they have no relationship with the users they are modeling. That, not surprisingly, makes the user suspicious. “Who are these people talking about me without my involvement!” That Google does the same thing for web sites and that we treat that as less offensive says something deep. Both how alienated we are from our sites; and it reminds one about the entire industry around self presentation (pr, search engine optimization, etc. etc.).

The key reason Double Click offends us is the fear that their model will bite us. While they maybe malicious they are almost certain to be cavalier. The concerns arises regarding Google and the models it builds of our sites. It can casually destroy them.

Nobody should continue to pretend that these gossip models can be avoided and that a handful of firms will have extensive ones. I wondered sometime ago if “you were king of Double Click could you fix this problem”? At the time it seemed to me that part of fixing it would be to begin to build a relationship with the users. I guess it will be interesting, as in “may you live in interesting times,” to see how Google tackles that problem. Hopefully they can do a better job that the credit reporting firms have. The puzzle is how to do that with the tools at hand: vast numbers of people and computers.

Leveraging the Notaries

I’ll note that much as one can use an SMS infrastructure to assert that a person has at least temporary control of a mobile phone you could use the existing notary system.    A service provider prepares a document instructs the user to print it, have notarized, and return to the service provider.

I wonder if that could be done in a manner that avoids revealing to the service provider any information other than the information contained in the document.  For example, could you keep the user’s name out of the service provider’s hands.

Internet Identity & the Public Notary

Solving coordination problems, in this case the internet identity problem, always involves leveraging some existing coordination framework. For example the PGP signing scheme leverages the acquaintance network and the signers are encouraged to leverage the government issued identity cards. For example my local library asks to see a utility bill, and thus leverages the account relationship I have with the utility.

When your designing one of these internet identity schemes you thrash around looking for something you might tie your raft to. The IP address, the browser cookie, the confirmed email address, etc. There are lots of clever schemes. For example Paypal does, or at least used to, do a cute trick where they would confirm that you had access to a bank account by making some tiny random deposits and then asking you to confirm their amounts. These days it’s common to see SMS messaging used to confirm you have control, at least for a moment or two, of a particular mobile phone number. I haven’t personally experianced, but I presume somebody has built, the phone equivalent of confirming an email address.

As usual these examples have three parties: entity to be identified, entity that desires that, and some third party: i.e. the user, the service, and the identity provider. When you confirm an email address the identity provider is the email infrastructure; and the reason the service finds that useful is it trusts that infrastructure; at a least somewhat. When a service confirm a mobile phone number using a SMS the SMS infrastructure is filling the role of identity provider. When a bar-keep checks a driver’s license he’s trusting that infrastructure; and his ability detect fraud.

The driver’s license is what in the digital world we might call a capability; it’s a token that grant’s it’s holder the right to perform various activities. Including, surprisingly and ironically, the ability to order a beer. We can make quite robust capability tokens in the digital world; but we need to have somebody sign them.

In the off-line world we have institutional infrastructure to support such signing. Quite a few actually. Financial industry, for example, has something they call a bank signature and if you take a random piece of paper down to a bank where you have an account the branch bank officer will be happy to watch you sign it, then they they will first press a large 3 dimensional stamp into the paper and then over that they will sign the paper too. Notary publics perform analogous services.

So. Let’s say I want to organize a large group of volunteers to provide some service for the general public. Let’s imagine that as part of this service the volunteers will be sending email to members of the general public with whom they have zero existing relationship; so the volunteers are concerned that they will be accused of spamming; or worse might get used due to a security flaw to actually spam.

I think the volunteers’ concerns could be addressed if I could give them a signed note from the user that grants them permission to pass on the email associated with the service. I.e. a capability token. But who would sign it?

I don’t think I’ve previously seen the idea of mimicking the notary public architecture before. It is just what’s needed. The service community selects some number of their members and anoints them as notable. Any notable person may gin up capablity tokens for a user. Any user wishing to use the service must seek out a notable person, acquire a signed capability token. The user can then distribute that token as they see fit.

The volunteers in a service community would want the notables governed well. That means at least: they are easy to find, cheap to use, courteous and professional in their manner, etc. Much that’s wrong with the existing key signing schemes arises from breakdowns (aka rent seeking) at this level.

But today I’m thinking that the real breakdown in those schemes was the choice to follow commercial models for the governance of the notables; rather than professional or fraternal models. I.e. non-profit. Or possible we should leverage state licensed models. Aside: there are millions of notary publics in the US.
I’m particularly enjoying the idea of a fraternal orders of signers in the tradition of Friendly Societies like the Odd Fellows, or Service Clubs like the International Order of Twelve Knights and Daughters of Tabor. Who wouldn’t want to be IKK, BJ, GS; aka an Imperial Knight of the Key, Boston Jurisdiction, GPG Affiliate. It would certainly come with a funny hat and a lapel pin.

Boston Marathon

I have a two concerns about the Boston Marathon, which is Monday.

We are forecast to have really horrible weather. I assume that if the weather was sufficiently horrible, 12 feet of snow, they would cancel. But? If they cancel the marathon does that mean everybody in Massachusetts has to have their taxes done on time, since as it is we get another day. Yes, yes, I know that nominally the reason we get another day is because Monday is a state holiday; i.e. patriot’s day. While Patriot’s day is no where as transparent a ploy as evacuation day (aka. St. Patrick’s) we are well on our way to treating Monday’s holiday as Boston Marathon day.

My second concern is fraud. Some years ago we had an extremely amusing case; a women won the marathon by sneaking onto public transportation to avoid running a portion of the race. Riders of the Boston transit system were amazed that was faster.

The usual response was taken; and millions of dollars were spent on technology to assure it those in high offices would never be accused of sloppy book keeping again. Today all runners carry RFID tags in their shoes.

But wait! We have now converted the entire Boston transit system so we use RFID tags for fare collection. I smell trouble!

VMWare, SBCL, Mac

There are a few ways to get a good Lisp environment under Mac OS X (including OpenMCL, SBCL, Lispworks, etc.). This is a note about yet another approach. We use VMWare to create a virtual machine, a guest. VMWare is currently free, since it’s in beta. In that guest machine we run Linux. We do that to get access to the network effect around the Linux Lisp community.

I tried doing this using FreeBSD. I like FreeBSD. But I took the immaturity of the threading on FreeBSD as a signal that the Lisp network on FreeBSD appears is weak.

I somewhat randomly picked the Gentoo variant of Linux because the Gentoo Lisp “portage” appears to be well populated. You can snarf a VMWare “virtual appliance” for Gentoo (400 megabytes). Which is good because the Gentoo folks seem to think that installing Gentoo should be a hazing ritual where in you prove you love the hardware more than your family.

All I wanted here was a Lisp process; i.e. a server. So I didn’t X, et. al. So I enabled ssh and set host only networking.

Once you have your guest Gentoo you need to bring it up to date. There are some rough instructions here. Portage is the gentoo community’s name for the infrastructure used to manage all the fun software you can install on your machine. Emerge is gentoo’s cute word for installing software and world is their word for the software on your machine. Getting your machine to be current is a two step process; which you do with the emerge command. First you need to get your portage system current, i.e. synchronize with the main line (emerge sync), and then you need to let emerge bring the world up to date (emerge world). That should be enough of a model to be able to understand what they are talking about in the gentoo wiki and doc.

It might be you could skip bringing it up to date, but you can’t skip installing the VMWare tools into the guest OS. There is doc in the VMWare manual (which you can skim), and doc on the gentoo wiki (which you must follow). You have to do this, otherwise the guest clock won’t be in sync with the host’s; and that will cause ASDF to recurse to death.

One clever feature of portage is that you can set some flags to modify the personality of the software that it installs. For example to indicate that you want doc, or gui support, etc. These flags are set in /etc/make.conf. Before installing any lisp software I set some of these to get the kind of lisp I needed. I added “threads unicode doc source” to the setting for USE in that file.

At this point you can install sbcl by doing ’emerge sbcl’. You can install slime/swank by doing ’emerge slime-cvs’.  emerge -p slime-cvs will not notice that the cvs repository has changed, so you may need to do ’emerge slime-cvs’ from time to time; to avoid having slime complain about protocol mismatching.  If you put doc in your make.conf USE, then the line ‘app-emacs/slime-cvs -doc’ in your /etc/portage/package.use; otherwise it will start huge tool chains to generate the doc.  I also have ‘dev-lisp/sbcl threads unicode -ldb’ in /etc/portage/package.use.
Presuming you want it to default to UTF-8 for sbcl external format on streams; do have ‘export LC_CTYPE=en_US.UTF-8′ in the environment before you run sbcl.
You’ll need a .sbclrc file; and it will likely want to include the usual gentoo initialization: ’emerge dev-lisp/gentoo-init’. My .sbclrc fires up swank; so I can connect to it from Aquamacs, running on the host mac. This is approximately what’s in my .sbclrc file. Note that by slamming the *loopback-interface* in swank it becomes possible for the host machine’s slime to connect into the guest machine’s swank listener; that’s safe because the vmware networking keeps the guest machine inaccessible from outside the host machine.

;;;; -*- mode: lisp -*-
(in-package "CL-USER")

;;; This is ~/.sbcl loaded by SBCL upon startup

;;; These make things nicer when debugging.
(declaim (optimize (safety 1)))
(declaim (optimize (debug 3)))

;;; Let gentoo's dev-lisp do it's thing.
(load "/etc/gentoo-init.lisp")

;;; Load swank and enable remote access.
(asdf:operate 'asdf:load-op 'swank)
(setf swank::*loopback-interface* "192.168.89.128")
(setf swank:*use-dedicated-output-stream* nil)
(setf swank:*communication-style* :fd-handler)
(swank:create-server :dont-close t :coding-system "utf-8-unix")

Once that's working you can proceed to install all the lisp packages you like; either via asdf-install or via emerge.

Note that the server is creted with a utf-8 coding system, that presumes that your emacs has utf support, fonts, and both (setf slime-net-coding-system 'utf-8-unix) (set-language-environment "UTF-8") are set before you connect.
I just use tramp, and sshfs via fuse.
All this was a lot more tedious than I'd imagined; but it works nicely now. And I have sbcl, threads, and unicode - which is a combination you can't get natively on the Mac right now. If I was a better person, if VMWare on the mac wasn't beta, and if I thought this set up had stabilized I would make a virtual appliance, a virtual lisp machine :), and post it.

Precarious Values

One of life’s puzzles is how to elicit desired behaviors. Managers, parents, leaders, what have you try out various schemes to address this puzzle. I sometimes characterise this as thrashing about looking for the right lever to pull. It’s not uncommon to see people deeply committed to a particular lever; metric management for example. The social sciences are replete with grand frameworks that outline a logic for this or that lever.

Somebody (thanks Chris) passed along this fun paper: “Organizational Adaption and Precarious Values: A Case Study” that frames up the problem in a nice way. “Precarious Values,” which I suspect was introduced (1956) here, is a lovely name for all the values which garner lip service but fail to attract supporting behaviors. That’s key. Members of this class are not in dispute, people agree that they are important and that they ought to acted upon; but they don’t actually get acted upon. They are precarious because it’s widely known that values that fail to be acted upon grow progressively weaker until they are extinguished entirely.

That something can be valued but then fail to garner it’s supporting behaviours is a delightful way of thinking about values. The puzzle of eliciting desired behaviors is situated right in the intersection between values and behaviors. Curiously it runs the other way; behaviors are quite skilled at attracting a portfolio of values to justify them. That’s a complementary problem, how do you bridge behaviors into well justified value?

So we have two problems. How are behavior’s elicited? How are values justified?

Not surprisingly I see the range of behaviors as being drawn from a highly skewed distribution and I’m mostly interested in the behaviors of groups. The value are, presumably, the stories the group tells about why it has adopted particular patterns of behavior. For example in open source communities we often tell the itch-scratch story and the many-eyes story to create a rational frame in support of common behaviors.  It’s notable that both those behaviors arose in advance of the values that latter explained them.

The precarious values are those with strong narratives, but which when mapped into the highly skewed distribution of behaviors are found in the lower middle-class. They get some attention but it appears that they don’t get attention in proportion to their supporting stories.

In open source such things might include obviously valuable activities such as testing, documentation, critical code reading, planning, design, accessibility, introductory examples, …    It’s a very long list, much longer than that, but then the lower-middle class is not a small population in any system.
Since behaviors are scarce there is competition between the values for supporting behaviors. There are patterns to that competition. The population of values is all struggling to negotiate out what behaviors will be elicited. Advocates for a particular set of behaviors are wise to seek allies. It’s a mistake to be too zealous in advocacy for one particular precarious value. Zealotry is not negotiation and it threatens all the other values. The other values maybe in competition but they can agree to band together to shun a particularly disruptive value in their community. Tempering the voice of a given value is difficult advice to take. A precarious value has – almost by definition – is broad consensus that it is valuable as it’s principle resource. Having voice but not action is an excellent climate for a storm of zealotry.

The case study in the paper is about adult education. The value that was made precarious, even to the point of extinction, was professionalism in the teaching staff. The story told is about how the state of California set out to provide a rich supply of continuing education. First to help emigrants to integrate with the large society more smoothly, but then to help assure that the citizens were better prepared to deal with the rapid rates of change in modern society (a problem that the economists sometimes describe as the need for high labor flexibility).

Structurally though adult education is a totally different beast from formal schooling. Adults are free, which youths are not. When the weather turns nice the adults tended not to show up. When running their finger down the catalog of course the adults tended to select course with more immediate pleasures (folk dancing, yoga) v.s. courses of a more professional nature (word processing, sales management). Meanwhile the instructors in youth oriented programs tended to be highly certified and thus well trained; while for many many reasons the instructors in the adult programs rarely were.

What’s fascinating about the story is that the precarious values in question (i.e. those of professional educators) were displaced. When the educational establishment advocated the creation of a large program for adult education they didn’t see it coming; but once the program had matured their professional values became first precarious and then finally entirely displaced.

Displacement is a natural fear for any given precarious value, but it isn’t the inevitable outcome. A precarious value can live on for years; since it has broad support. In open source, for example, both planning and documentation live on as precarious values. Both tend to elicit sufficient behaviors to keep them alive.

Recognizing that there is a struggle between values being played out in any community was quite enlightening but there is something more fundamentally interesting. It looks to me like the stories communities tell about their strong values are monuments to past struggles upon this plane. For example the itch-scratch story is almost a shrine we in the open source community visit to remember those days, now past, when the idea of letting some random user tinker with the code in an apparently whimsical manner was it’s self a precarious value.

Want to get cited? Write an old paper.

citations_vs_year.png

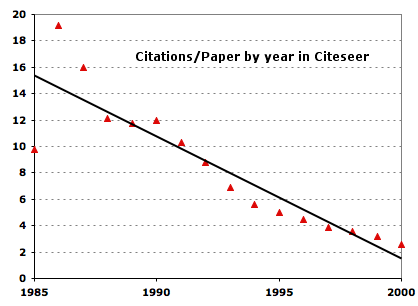
This chart shows the average number of citations papers in a given year have garnered since their publication. Again this is the citeseer data.

Let me those offer three very tentative explanations.  I’m sure people can come up with more.  Presumably, it’s easier to write a fundamental, useful, provocative paper when a field is young. Preferential attachment effects help older papers to bank more citations. Noting how few papers are in the collection in 1985 I suspect the collection manager is seeking out the papers from that era and starting with those that are cited.

Citeseer Year of Publication

citeseer_pubyear1.png
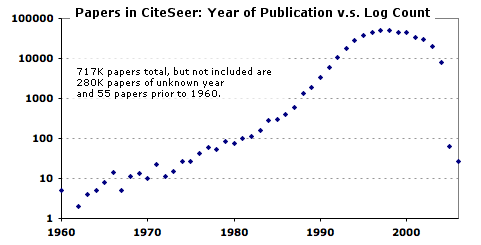
I guess I don’t have any idea what universe Citeseer’s collection actually covers, or attempts to cover. I think it’s papers in Computer Science. I think it attempts to be the entire universe of such papers.

You can down load a dump of their catalog in XML. The copy I got has 717,172 publication ids in it. Many of those have a publication data recorded; and most of those are plotted above.

Looks like the exponential growth in these publications came to an end in the 1990s.

Theories anybody? Extra points for amusing theories. For example they all decided to post at Wikipedia and their blogs instead. Or the opportunities in the web space highly distracting, but made lousy papers. Maybe Microsoft hired everybody and drew a curtain around their work.